Abstract
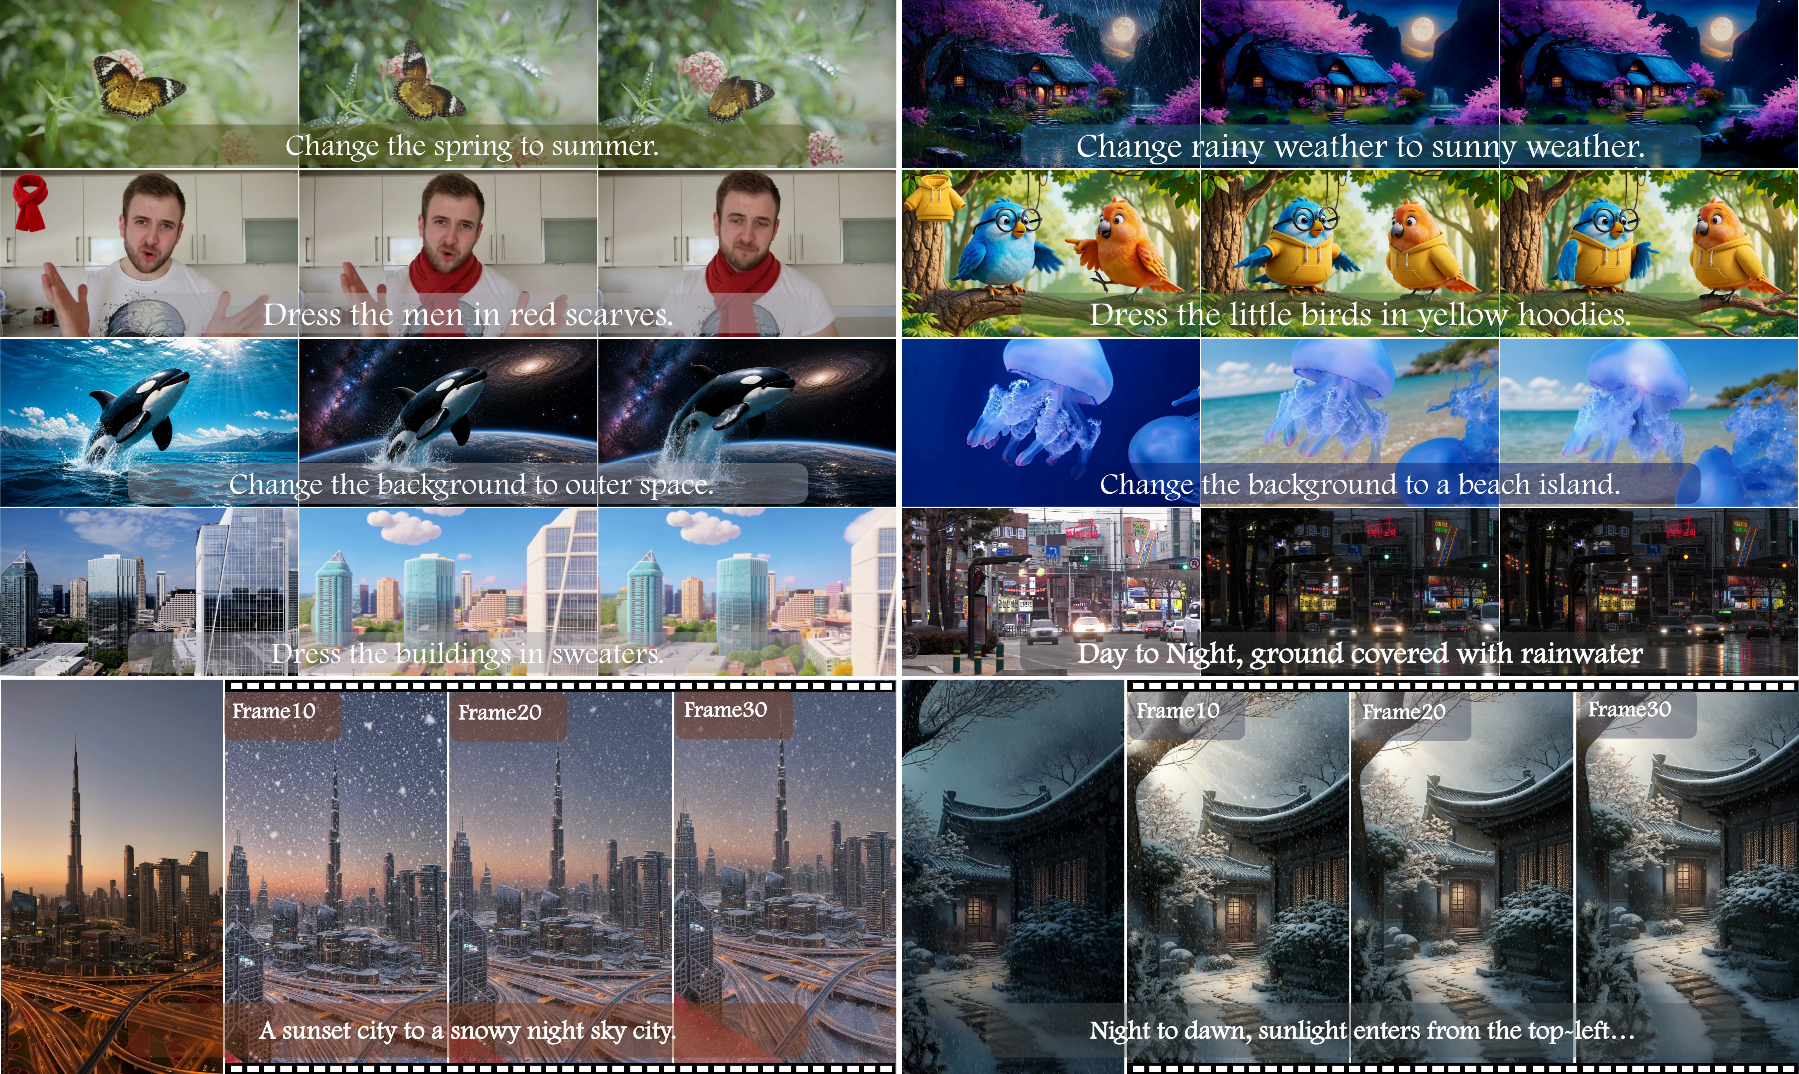
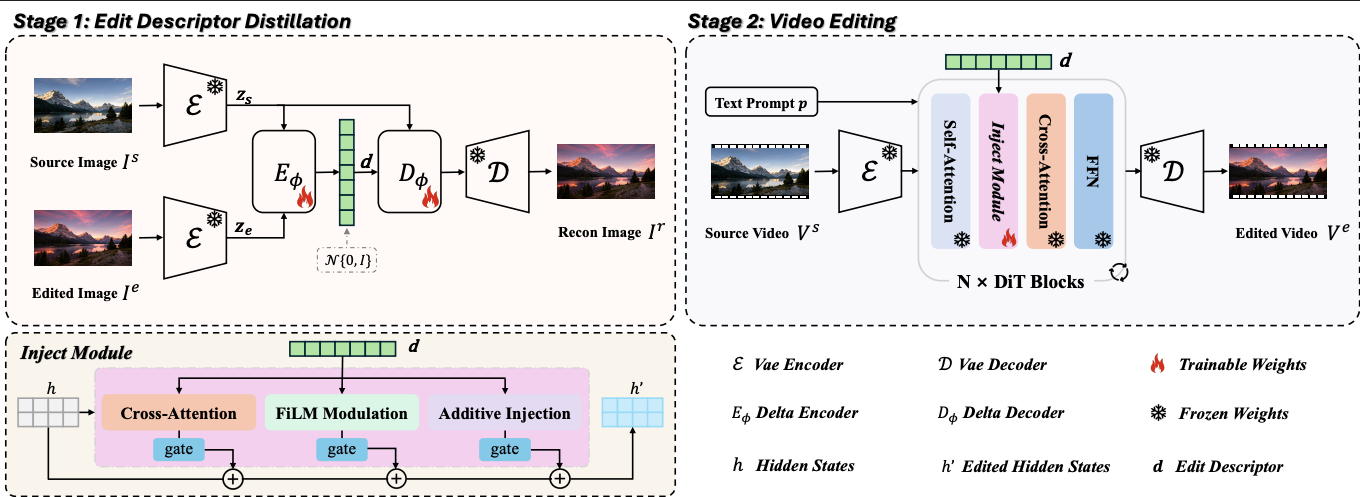
We study exemplar-driven video editing: given an image pair that demonstrates a visual transformation and a source video depicting a related subject, generate an edited video that preserves temporal dynamics while transferring the demonstrated change. We present EditDistill, a two-stage framework that first distills the edit shown by the image pair into a compact latent delta and then injects that delta into a pre-trained video diffusion transformer built on Wan2.1-I2V-14B. The first stage learns an edit representation by reconstructing the target image from the source image and an inferred latent change code. The second stage uses lightweight injection modules to condition selected transformer blocks on that code, enabling controllable video-to-video editing without full backbone retraining. This decomposition separates edit specification from temporal rendering, supports reusing the same edit delta across multiple videos, and exposes explicit control over edit strength and injection strategy. We further define an evaluation protocol that measures edit fidelity, temporal consistency, controllability, and efficiency, thereby turning exemplar-based video editing into a concrete and reproducible empirical problem.
Overview
Visualization Results
Different Types of Building Dressing
Various Season Editing
Various Object Editing
Editing Comparison